Strategies for Collaboration, Autonomy, Learning, and Exploration in Robotics Lab
Director: Dr. Rohan Paleja

Our lab advances machine learning and artificial intelligence to improve robot learning, human-robot interaction, and multi-agent coordination.

  • Interactive Robot Learning: Developing computational approaches to help humans teach new behaviors or correct existing ones.
  • Explainable Robotics: Imbibing robotic systems with decision-making capabilities that can be understood, traced, and trusted by humans.
  • Multi-Agent Coordination: Developing methods that enable teams of robots and humans to communicate and collaborate in complex environments.
Research Areas

Imitation Learning

Learning from demonstration and interactive robot learning frameworks.

Explainable AI

Interpretable AI, transparent policies, and rigorous system validation.

Multi-Agent RL

Heterogeneous multi-agent coordination, reinforcement learning, and communication.

Human-Machine Teaming

Algorithmic HRI, ad hoc teaming, and mutual understanding architectures.

Recent News

Publications

* denotes equal contribution. Blue - Conference. Orange - Journal. Pink - Workshop/Other.

Mitigating Retaliatory Algorithmic Collusion in Repeated Games

Karthik Sivachandran , Rohan Paleja

NeurIPS 2026 Conference on Neural Information Processing Systems (NeurIPS), 2026.


Differentiable Belief-based Opponent Shaping

Aarav Sane , Karthik Sivachandran , Rohan Paleja

NeurIPS 2026 Conference on Neural Information Processing Systems (NeurIPS), 2026.


Event-Grounded Sparse Autoencoders for Vision-Language-Action Policies

Xinchen Jin , Aditya Chatterjee , Pranav Kumar , Rohan Paleja

NeurIPS 2026 Conference on Neural Information Processing Systems (NeurIPS), 2026.


Mechanistic Interpretability for End-to-End Self-Driving

Manav Gagvani , Benjamin Namikas , Sivamurugan Velmurugan , Nysa Kumar , Shrey Sharma , Thomas Peterson , Pratyush Mathur , Hyunseo Chang , Rohan Paleja

CoRL 2026 Conference on Robot Learning (CoRL), 2026.
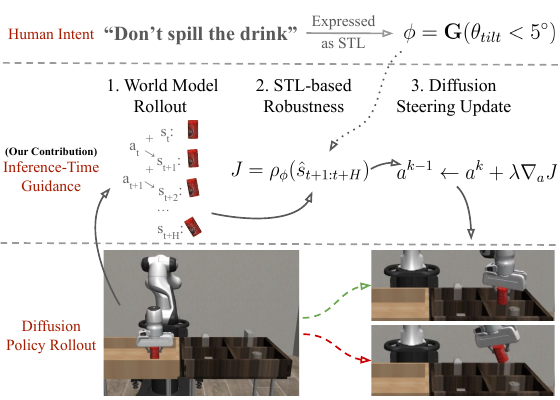

Teaser for Temporal Logic Guidance for Action-Only Diffusion Policies with World Models
Temporal Logic Guidance for Action-Only Diffusion Policies with World Models

Moritz Zoellner , Anastasios Manganaris , Rohan Paleja

ICRA W. 2026 ICRA 2026 Workshop on Bridging the Gap between Robot Learning and Human-Robot Interaction
Diffusion policies enable multimodal robot behavior but offer limited ability to choose among behavior modes at inference time, even though such control is desirable in human-robot settings. Prior solutions to this lack of control have utilized Signal Temporal Logic (STL) to express human intentions and provide corresponding guidance for diffusion policy inference. However, these approaches can only guide diffusion policies that jointly generate future actions and states, increasing both complexity and runtime. We propose a novel guidance method for action-only diffusion policies that uses a separate learned world model to enable differentiable evaluation of STL robustness, with its gradient then injected into the diffusion process. This steers behavior toward constraint satisfaction without retraining, improving constraint adherence while preserving task performance. On the Can Transport task from Robomimic, our method maintains 100% task success while reducing constraint violations from over 80% for baseline methods to 4%. We also discuss extensions toward improved robustness and more complex constraints.

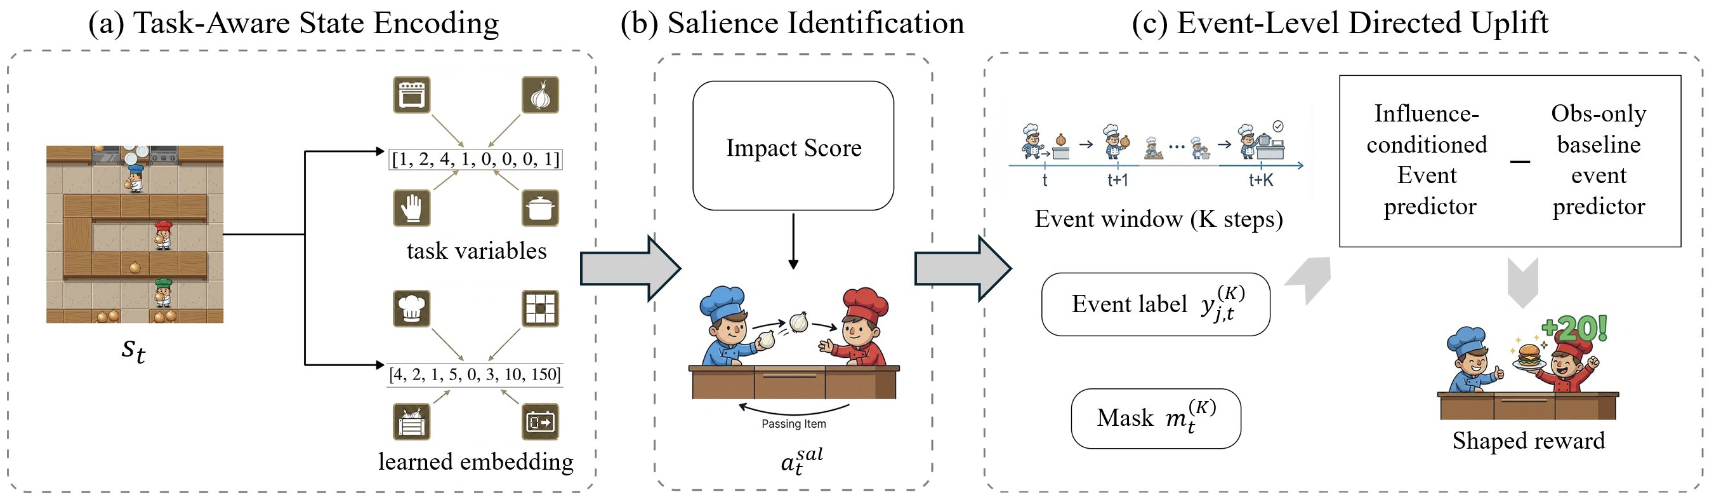
Teaser for Influence-Salient Coordination Shaping for Scalable Cooperative MARL
Influence-Salient Coordination Shaping for Scalable Cooperative MARL

Wei Sheng , Rohan Paleja

ICLR W. 2026 ICLR 2026 Workshop on AI for Mechanism Design and Strategic Decision Making
Interaction-driven coordination is central to real-world teamwork, yet cooperative multi-agent reinforcement learning often struggles to induce it. This difficulty compounds as agent populations scale, since decentralized learning and weak credit assignment under combinatorial interaction structures can yield brittle, loosely coupled routines with limited mutual responsiveness. To tackle these challenges, we propose Influence-Salient Coordination Shaping (ISCS), a scalable shaping mechanism for learning team coordination in cooperative multi-agent systems. ISCS identifies influence-salient choices by selecting actions that maximize expected transition displacement in a learned representation space, then computes a directed, baseline-adjusted uplift-based shaping bonus that rewards actions increasing the likelihood of subsequent teammate coordination beyond what the joint observation alone predicts. To reduce timing sensitivity, ISCS optimizes uplift over a short-horizon coordination event rather than requiring an immediate next-step response, improving robustness to delayed responses and reducing spurious attribution from state-induced correlations. Experiments on challenging cooperative benchmarks show that adding ISCS to standard CTDE methods improves sample efficiency and final performance over strong baselines.

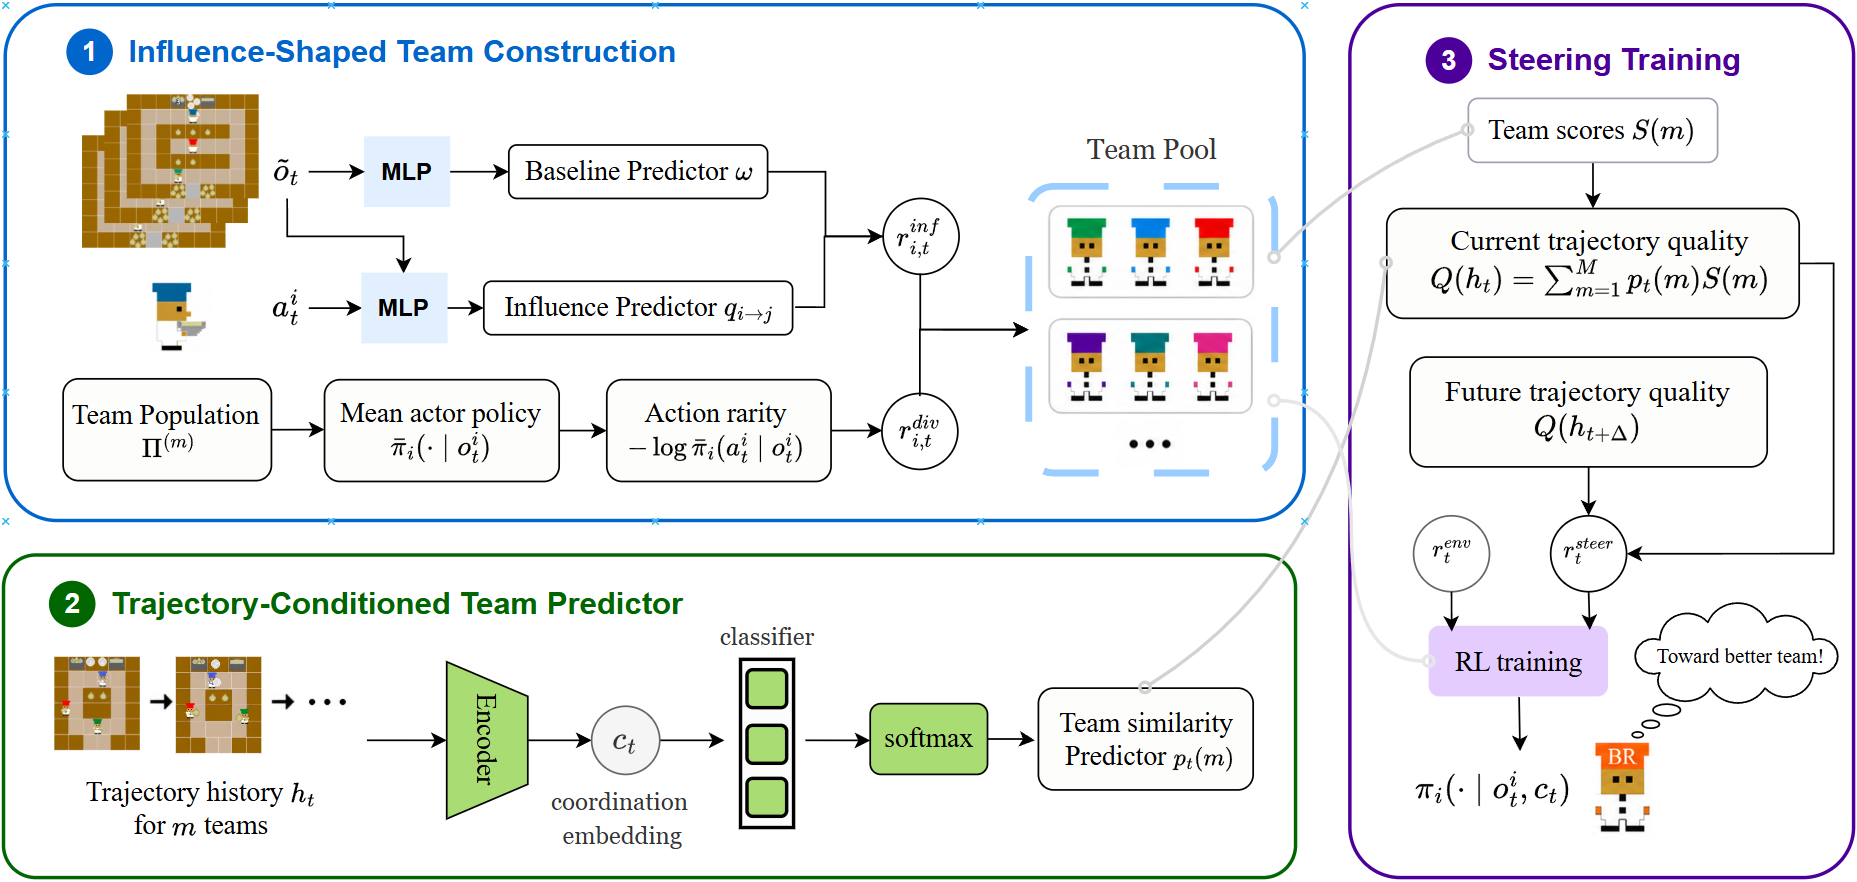
Teaser for Beyond Partner Diversity: An Influence-Based Team Steering Framework for Zero-Shot Human-Machine Teaming
Beyond Partner Diversity: An Influence-Based Team Steering Framework for Zero-Shot Human-Machine Teaming

Wei Sheng , Rohan Paleja

arXiv 2026 arXiv CS.

While AI agents are rapidly advancing from isolated tools to interactive collaborators, data-driven human-machine teaming (HMT) methods remain costly in their reliance on human interaction data across domains, teammates, and team sizes. Zero-shot coordination (ZSC) addresses this bottleneck by simulating diverse partner populations to approximate how unseen partners might behave. However, partner coverage alone is insufficient as team settings scale and communication becomes degraded. To remedy this deficiency, we propose Influence-Based Team Steering (IBTS), a framework that uses influence shaping to incentivize agents to discover diverse, high-performing team interaction patterns and further steers ongoing trajectories toward stronger learned coordination modes. We assess IBTS on Overcooked-AI in both two-agent and three-agent settings, allowing us to test whether learned coordination structure transfers beyond dyadic interaction. Our evaluation includes simulated partners, synthetic partner-style variation, and, to our knowledge, the first 30-subject Overcooked-AI HMT study involving two real human teammates and one machine teammate. Across these evaluations, IBTS improves team performance against competing baselines, highlighting the need for scaled ZSC to combine sparse-reward coordination mechanisms with partner-variation coverage rather than relying on diversity alone.

Get In Touch

If you'd like to discuss research, collaborations, or opportunities, feel free to reach out!

Email: rpaleja@purdue.edu for all inquiries

You can also find me on:

Google Scholar GitHub LinkedIn Twitter